Configuring and Running Optimizations#
The neps.run() function is the core interface for running Hyperparameter
and/or architecture search using optimizers in NePS.
You can find most of the features NePS provides through the API of this function.
This document breaks down the core arguments that allow users to control the optimization process in NePS.
Required Arguments#
To operate, NePS requires at minimum the following two arguments
neps.run(evaluate_pipeline=..., pipeline_space=...):
import neps

def evaluate_pipeline(learning_rate: float, epochs: int) -> float:
    # Your code here
    return loss

class ExamplePipeline(neps.PipelineSpace):
    learning_rate = neps.Float(1e-3, 1e-1, log=True)
    epochs = neps.IntegerFidelity(10, 100)

neps.run(
    evaluate_pipeline=evaluate_pipeline, # (1)!
    pipeline_space=ExamplePipeline(), # (2)!
    root_directory="path/to/result_dir" # (3)!
)
- The objective function, targeted by NePS for minimization, by evaluation various configurations. It requires these configurations as input and should return either a dictionary or a sole loss value as the output.
- This defines the search space for the configurations from which the optimizer samples.
It accepts a class instance inheriting from
neps.PipelineSpaceor aconfigSpace.ConfigurationSpaceobject. For comprehensive information and examples, please refer to the detailed guide available here - The directory path where the information about the optimization and its progress gets stored.
This is also used to synchronize multiple calls to
neps.run()for parallelization.
See the following for more:
- What kind of pipeline space can you define?
- What goes in and what goes out of
evaluate_pipeline()?
Budget, how long to run?#
To define a budget, provide total_evaluations_to_spend= to neps.run(),
to specify the number of evaluations after which the whole study (across all workers) stops,
and/or total_cost_to_spend= to specify a cost threshold for your own custom cost metric, such as time, energy, or monetary, as returned by each evaluation of the pipeline,
and/or total_fidelities_to_spend= for multi-fidelity optimization, to specify the total fidelity to spend.
Each of these also has a worker_ variant (e.g. worker_evaluations_to_spend=) that limits only what a single neps.run() call/worker does.
def evaluate_pipeline(learning_rate: float, epochs: int) -> float:
    start = time.time()

    # Your code here
    end = time.time()
    duration = end - start
    return {"objective_function_to_minimize": loss, "cost": duration}

neps.run(
    total_evaluations_to_spend=10, # (1)!
    total_cost_to_spend=1000, # (2)!
)
- Specifies the total number of evaluations a worker is allowed to perform before halting the optimization process.
- Prevents the worker from initiating new evaluations once this cost threshold is exceeded.
This can be any kind of cost metric you like, such as time, energy, or monetary, as long as you can calculate it.
This requires adding a cost value to the output of the
evaluate_pipelinefunction, for example, return{'objective_to_minimize': loss, 'cost': cost}. For more details, please refer here
Getting some feedback, logging#
NePS will not print anything to the console. To view the progress of workers, you can enable logging through python's logging.basicConfig.
Please refer to Python's logging documentation for more information on how to customize the logging output.
Live plots#
Pass live_plots=True to have NePS redraw the plots in root_directory/summary/ after
every evaluated trial: the incumbent trajectory, or the Pareto front for two objectives,
plus anything your optimizer provides.
It is off by default, since every refresh redraws the figures. You can always get the same
plots later with
neps.analyze(root_directory). See Analysing Runs.
Continuing Runs#
To continue a run, all you need to do is provide the same root_directory= to neps.run() as before,
and specify a new stopping criterria(e.g. through total_evaluations_to_spend= and/or total_cost_to_spend=).
def run(learning_rate: float, epochs: int) -> float:
    start = time.time()

    # Your code here
    end = time.time()
    duration = end - start
    return {"objective_to_minimize": loss, "cost": duration}

neps.run(
    # enable stoping criteria by specifying new number of evaluation desired.
    total_evaluations_to_spend=50,
)
If a previous run stopped because a worker exhausted its budget, and you restart the run with the same stopping criterion, each worker will again be allowed to spend up to that budget on new evaluations.
As a result, when running multiple workers or restarting a run, the total resource usage may exceed the originally intended global budget. If you have global resource constraints (for example, total cost or total number of evaluations across all workers), you are responsible for tracking and enforcing them externally.
Auto-loading
When continuing a run, NePS automatically loads the search space and optimizer configuration from disk. You don't need to specify pipeline_space= or optimizer= again - NePS will use the saved settings from the original run.
Reconstructing and Reproducing Runs#
Sometimes you want to inspect what settings were used in a previous run, or reproduce a run with the same or modified settings. NePS provides utility functions to load both the search space and optimizer information:
import neps

# Load everything from a previous run
root_dir = "path/to/previous_run"

pipeline_space = neps.load_pipeline_space(root_dir)
optimizer_info = neps.load_optimizer_info(root_dir)

print(f"Original optimizer: {optimizer_info['name']}")
print(f"Original search space: {pipeline_space}")

# Option 1: Continue the original run (auto-loads everything)
neps.run(
    evaluate_pipeline=my_function,
    root_directory=root_dir,
    total_evaluations_to_spend=10,  # adjusted new budget
)

# Option 2: Start a new run with the same settings
neps.run(
    evaluate_pipeline=my_function,
    pipeline_space=pipeline_space,
    root_directory="path/to/new_run",
    optimizer=optimizer_info['name'],
    total_evaluations_to_spend=50,
)
For details on:
neps.load_pipeline_space()- see Search Space Referenceneps.load_optimizer_info()- see Optimizer Reference
Overwriting a Run#
To overwrite a run, simply provide the same root_directory= to neps.run() as before, with the overwrite_root_directory=True argument.
Warning
This will delete the folder specified by root_directory= and all its contents.
Getting the results#
The results of the optimization process are stored in the root_directory=
provided to neps.run().
The root directory after utilizing this argument will look like the following:
root_directory
├── configs
│   ├── config_1            # Could also be config_1_rung_0 for multi-fidelity
│   │   ├── config.yaml     # The configuration
│   │   ├── report.yaml     # The results of this run, if any
│   │   └── metadata.json   # Metadata about this run, such as state and times
│   └── ...
├── summary
│   ├── full.csv
│   ├── short.csv
│   ├── best_config_trajectory.txt
│   ├── best_config.txt
│   └── ...                 # Plots, with live_plots=True or neps.analyze()
├── optimizer_info.yaml     # The optimizer's configuration
├── optimizer_state.pkl     # The optimizer's state, shared between workers
└── ...                     # Other neps files
To check on a run use neps.status, and to (re)generate its plots and reports at any time
use neps.analyze(root_directory). You can also log to TensorBoard from inside your
training loop. For more information, please refer to the analyses page.
Parallelization#
NePS utilizes the file-system and locks as a means of communication for implementing parallelization and resuming runs.
As a result, you can start multiple neps.run() from different processes however you like
and they will synchronize, as long as they share the same root_directory=.
Any new workers that come online will automatically pick up work and work together to until the budget is exhausted.
Interactive tutorial
The Parallelization section of the Efficient Optimization tutorial runs a single worker and then three parallel workers sharing one root_directory.
# worker.py
neps.run(
    evaluate_pipeline=...,
    pipeline_space=...,
    root_directory="some/path",
    worker_evaluations_to_spend=100, # (1)!
    continue_until_max_evaluation_completed=True, # (2)!
    overwrite_root_directory=False, #!!!
)
- Limits the number of evaluations for this specific call of
neps.run(). - Evaluations in-progress count towards worker_evaluations_to_spend, halting new ones when this limit is reached.
Setting this to
Trueenables continuous sampling of new evaluations until the total of completed ones meets worker_evaluations_to_spend, optimizing resource use in time-sensitive scenarios.
Warning
Ensure overwrite_root_directory=False to prevent newly spawned workers from deleting the shared directory!
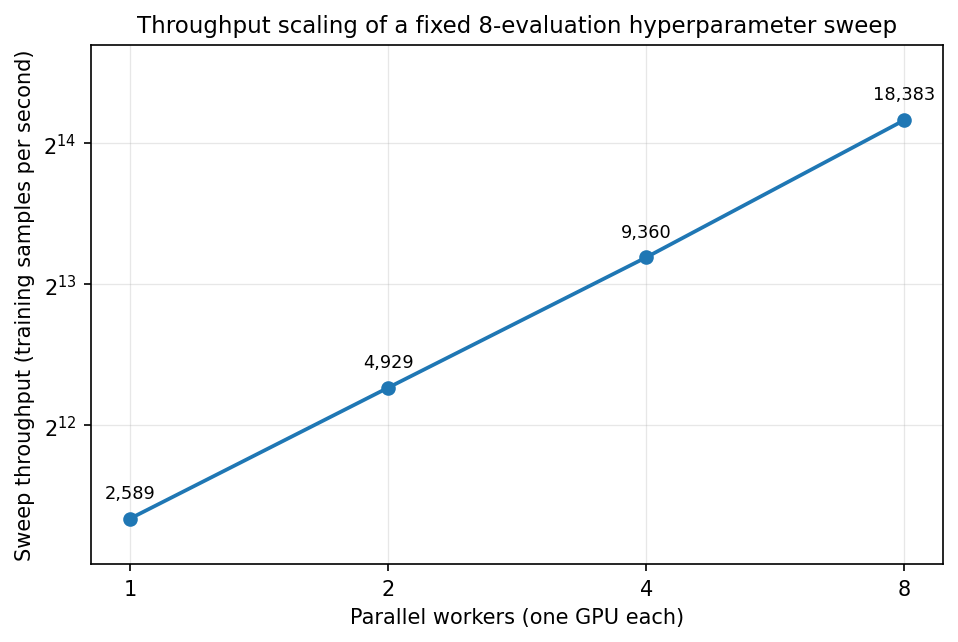
Adding workers scales the throughput of a sweep almost linearly: in our VLM example, 8 workers (one GPU each) run the same 8-evaluation sweep about 7× faster than one.
Handling Errors#
Things go wrong during optimization runs and it's important to consider what to do in these cases.
By default, NePS will halt the optimization process when an error but you can choose to ignore_errors=.
def run(learning_rate: float, epochs: int) -> float:
    if whoops_my_gpu_died():
        raise RuntimeError("Oh no! GPU died!")

    ...
    return loss

neps.run(
    ignore_errors=True, # (1)!
)
- Continue the optimization process even if an error occurs, otherwise throwing an exception and halting the process.
Note
Any runs that error will still count towards total_evaluations_to_spend.
Re-running Failed Configurations#
Sometimes things go wrong but not due to the configuration itself. If you want to reset failed or crashed trials so they get re-evaluated, use the neps clean command:
This resets all failed, crashed, and corrupted trials in your working directory back to pending, keeping their configs. To reset specific trials by ID:
You can preview what would change with --dry-run:
If you'd rather remove the trials entirely instead of resetting them, pass --delete.
Once cleaned, you can restart the optimization and workers will pick up from the cleaned state.
For more details on the clean command, see the Cleaning Up Trials documentation.
Selecting an Optimizer#
By default NePS intelligently selects the most appropriate optimizer based on your defined configurations in pipeline_space=, one of the arguments to neps.run().
The characteristics of your search space, as represented in the pipeline_space=, play a crucial role in determining which optimizer NePS will choose.
This automatic selection process ensures that the optimizer aligns with the specific requirements and nuances of your search space, thereby optimizing the effectiveness of the hyperparameter and/or architecture optimization.
You can also manually select a specific or custom optimizer that better matches your specific needs. For more information about the available optimizers and how to customize your own, refer here.